
Pinterest Transitions to 4B Qwen3 LLM for User Journey Inference, Reports Increased Engagement
Pinterest has moved its user-journey inference system from a multi-stage clustering pipeline to a fine-tuned 4-billion-parameter language model, reporting a 1.1% improvement in email click-through rates and a 1.3% increase in push notifications opens.
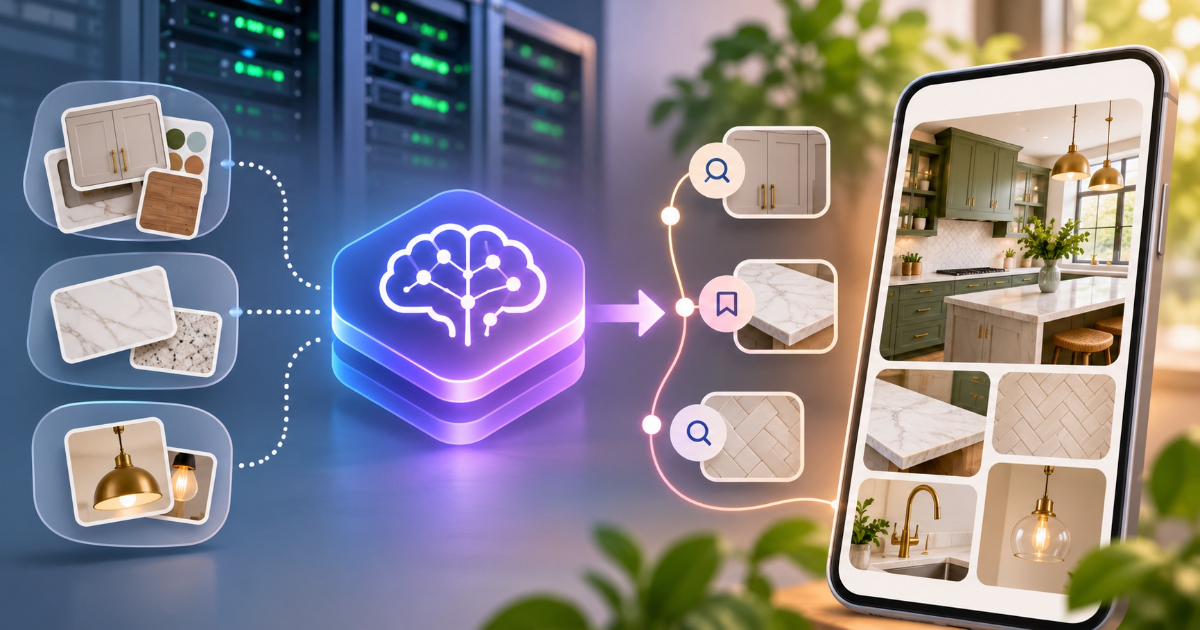
Instead of clustering keywords into interests, the new model analyzes users’ activity histories to identify long-term goals and integrates these journeys into Pinterest’s existing recommendation system.
Pinterest defines a “journey” as a goal that connects interests, intent, and context across multiple sessions. For example, a user renovating a kitchen might search for cabinet designs, save countertop ideas, and later explore backsplash tiles or lighting. These interactions suggest a coherent project rather than several unrelated interests.
The previous system extracted keywords from user activity, grouped them using embeddings and hierarchical clustering, named the resulting clusters, and ranked them with additional models and diversity heuristics. Although this method was effective compared to earlier interest-based notifications, it could fragment related activities into separate journeys and produce generic labels.
The new system treats journey inference as a generation task. A fine-tuned LLM reads a chronological history of up to 150 user actions over a 360-day window, alongside a compact user profile, generating a ranked set of journey names. Actions such as searches and saves are weighted more heavily than incidental clicks, with the model instructed to consider repeated engagement, recency, and specificity.
This consolidation moved much of the previous system’s ranking and filtering behavior into the prompt. Instructions discourage unrelated interests from merging, suppress one-off activities and noisy automatically generated tags, and allow for empty results when there is insufficient evidence of a meaningful journey. Pinterest treats changes to these instructions as production launches rather than simple prompt edits.
To build the system without an extensive human-labeled dataset, Pinterest utilized frontier models to generate synthetic training examples from its user activity histories. These examples were used to fine-tune smaller open-weight Qwen3 models through supervised fine-tuning and low-rank adaptation (LoRA).
The team tested models ranging from 0.6 billion to 8 billion parameters, ultimately selecting the 4 billion parameter model for its balance of inference quality and serving throughput.
Running the resulting model at Pinterest’s scale presented additional engineering challenges. The company deployed NVIDIA Dynamo in front of vLLM workers operating on L40S GPUs, employing continuous batching, PagedAttention, and prefix-cache-aware routing.
Source: InfoQ